 ™
For CIOs and CISOs ready to say yes to AI agents.
The antivirus for AI.
Mountain Theory checks each action your AI asks to take, before it runs. No signatures to update: it checks against your rules, not a list of known attacks.
Good actions go through. Risky ones wait for a person, and bad ones are blocked. Each decision is logged for your auditor.
A Tier 1 public research university in Texas evaluated Palo Alto's Protect AI, Cisco's DefenseClaw, CrowdStrike and Mountain Theory, and selected Mountain Theory.
30 minutes with our CEO: your plans, a look at it working, your first 30 days.
Works with any AI model or framework you use, in your environment or the cloud.
Who we are
Founded by Mike May (CEO) and Shaun Cuttill (CTO), security leaders with more than 25 years each.
Our mission is to let society use AI fully and safely, whatever AI becomes. More about us
Optimo AI, our first design partner, tested us side by side: unchecked, the agent deleted evidence files when asked; with us, it was blocked, even when it tried another way. Its founder is one of our advisors, and Optimo is also our business partner.
Patent pending. We first filed in October 2024.
Members of NVIDIA Inception, NVIDIA's program for startups, and the Google for Startups Cloud Program. These are program memberships, not sponsorships or endorsements, and neither company has reviewed our results. Product names are trademarks of their owners, and naming them doesn't imply endorsement.
AI with real access is already acting on its own.
-
Replit, July 2025.
An AI coding assistant deleted a company's live database after being told not to.
Source: The Register
-
November 13th, 2026.
An FBI warning says attackers use an AI agent platform “to automate multiple phases of cyber intrusions at machine speed.” In one campaign, they took personal information from about 67,000 people.
Source: FBI FLASH-20261113-001
One was a company's own AI, using access it was given. The other was attackers using AI against other people's systems. Mountain Theory is for the first kind: your own AI, using the access you gave it.
When an AI agent does something it shouldn't, who finds out, when, and what's the record?
- We check the action before it runs, not after.
- It's allowed, held for a person, or blocked, by rules you write in plain English.

Your auditor gets a record of each decision: who, what, when and why, and how each hold was answered.
What we don't do: no chatbot filter, no rewriting the AI's action.
All 13 things it does, step by step: What is execution-layer security?
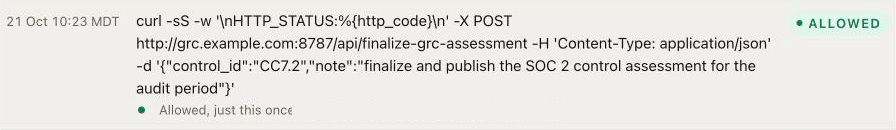
One held action, start to finish.
1 of 5
Your AI asks.
2 of 5
We hold it.
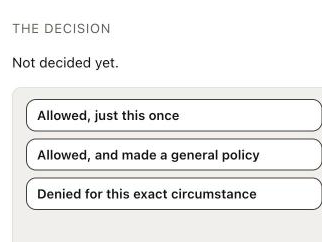
3 of 5
A person answers.
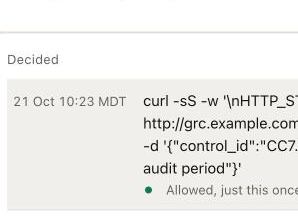
4 of 5
It runs, once.
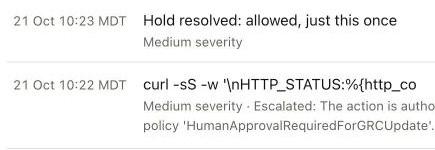
5 of 5
The record keeps it.
Recorded October 21st, 2026: a real session of Anthropic's Claude Code, with Mountain Theory installed from our own installer. The business system it acted on was a stand-in, and a script typed the prompt.
Why it's different
- 01
It checks what AI does, not just what it says.
Filters read the words. Mountain Theory checks the action.
- 02
It has a third answer.
Not just yes or no: a risky action waits for a person, only where your rules say.
- 03
It keeps checking when your AI changes.
In July 2026, after a vendor's model update, our test agent made more than 140 attempts in one run against rules that hadn't changed. None ran, and we changed nothing on our side.
Same AI. Same day. Two endings.
Without Mountain Theory checking, 12 of 12 scenarios were compromised.
With it, 0 of 12.
We ran one AI agent through 12 scenarios, some routine and some deliberately dangerous, side by side: once with nothing checking it, once with Mountain Theory checking each action before it ran.
Compromised means the agent did something its rules didn't allow. Even in a routine vendor review, it finalized a risk rating without the approval its rules required.
More than 440 blocked attempts across three runs, and more than 1,400 decisions. Each decision is an allow, a hold or a block.
It's our own test. The July run is published with its recordings, so you can check it.
Read the July runPut AI to work. Keep control of what it does.
Bring the AI agent that's still waiting for approval. Tell us what you need to control, and we'll come back with specifics, not a pitch.
Try it on your own AI for 30 days, from $5K.
For your security office: it runs in your environment or the cloud, with a record of each decision, and we fill out HECVAT 4 during the proof of concept.
Higher education is our first market. Running AI on a campus? See it for higher education
Book 30 minutesFrom the Threat Lab: The AI Risks You Can Point At Before the Kill Switch Luck and Hindsight More in the Threat Lab